
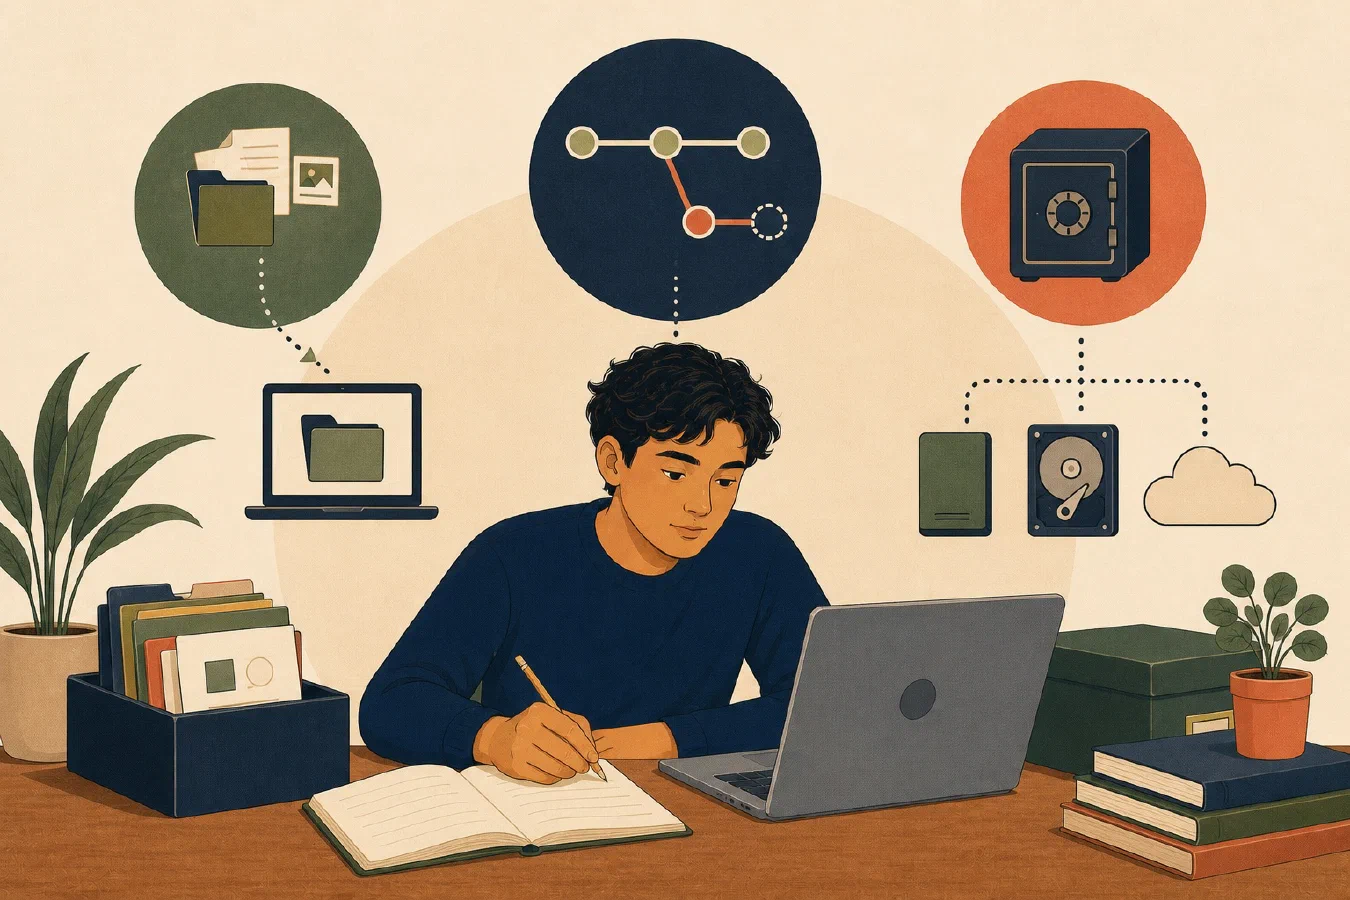
Sync, Git, and backup can all create additional copies of data, but they solve different problems. Sync keeps selected files available across locations. Git records deliberate versions of a project. Backup preserves recoverable copies for loss or damage. A reliable student system assigns each layer a specific job.
Why one extra copy is not enough
Suppose a student keeps a programming project in a synchronized folder. The folder appears on a laptop and in a cloud service. This helps when the student moves between devices. It does not answer every recovery question:
- What if an unwanted deletion synchronizes to both locations?
- What if yesterday’s working code must be compared with today’s broken code?
- What if the account is inaccessible?
- What if important files were never included in the synchronized folder?
No product label settles these questions. The useful test is what failures the system can recover from and how the student has verified that recovery.
Synchronization keeps locations aligned
Synchronization copies changes between selected locations so that they converge on a current state. A change made on one device may appear on another device and in the service that coordinates them.
Sync is useful for:
- opening current notes on more than one device;
- continuing work after switching computers;
- sharing a current folder when collaboration is intended; and
- reducing dependence on one local storage device.
Its strength is also its limitation. A deletion, rename, or unwanted edit may propagate. Some services retain earlier versions or deleted items, but retention rules and recovery interfaces vary. Treat those features as capabilities to verify, not assumptions.
Git records deliberate project history
Version control records changes to a file or set of files over time. Git stores committed project states as snapshots, which lets you compare versions and return to a recorded state. The official Pro Git explanation of version control describes this purpose, while its Git data model explains snapshots and the local repository.
Git is useful for:
- source code and text-based project files;
- intentional checkpoints;
- line-by-line comparison;
- branches and controlled experiments; and
- collaboration through shared repositories.
Git does not automatically protect every file on a computer. Untracked files, uncommitted changes, ignored files, course downloads, photos, and application data may be absent. A repository stored only on one damaged device can also be lost. A remote repository adds another copy of recorded history, but account access, repository scope, and unpushed work still matter.
Use Git for project history, not as a claim that the whole device is backed up.
Backup preserves data for recovery
NIST defines a backup as a copy of information, files, and programs made to facilitate recovery. A backup process selects important data, creates recoverable copies, retains them according to a schedule, and provides a restoration method. See the NIST small-business cybersecurity glossary.
Backup is useful for:
- device loss or storage failure;
- deletion or corruption discovered after some time;
- files outside synchronized or version-controlled folders;
- preserving semester-end archives; and
- rebuilding after a larger incident.
A backup is not defined by a particular disk or cloud service. Its value depends on scope, separation, retention, access, and tested restoration.
Match the layer to the failure
| Situation | Sync | Git | Backup |
|---|---|---|---|
| Continue a current note on another device | Primary layer | Usually unnecessary | Recovery layer |
| Compare two committed versions of code | Not designed for this | Primary layer | May recover an older copy |
| Recover an uncommitted file after device loss | Only if it synchronized | Usually cannot | Primary layer if included |
| Undo a deletion that propagated everywhere | Maybe, if retention exists | Only if tracked and committed | Primary layer |
| Recover an entire academic folder after drive failure | Maybe, for included files | Only repositories and recorded content | Primary layer |
| Explain why a program changed | No | Commit history and diffs | No |
The table shows why the layers overlap without becoming interchangeable.
Build a three-layer protection plan
Choose one important folder, such as college/2026-fall/cs101/, and complete
this plan:
# Protection plan: CS 101

## Scope
- Source code, notes, assignments, and instructor-provided files
- Exclude temporary build output that can be regenerated

## Synchronization
- Location or service:
- Included paths:
- How I verify current files reached the second location:
- Retention or deleted-file behavior I still need to check:

## Git
- Repositories:
- Files intentionally tracked:
- Commit checkpoint:
- Remote location, if used:
- Work that Git does not include:

## Backup
- Backup destination:
- Schedule:
- Retention:
- Recovery information stored separately:
- Last successful restoration test:

## Failure checks
- If the laptop is lost:
- If I delete the wrong folder:
- If I need last week's program:
- If my main account is inaccessible:
Do not list a tool without stating what it protects. “Stored in the cloud” does not identify included files, history, retention, or recovery access.
Common mistakes
- Treating sync as backup. Propagated changes can affect every synchronized location.
- Treating a Git remote as whole-device protection. Git covers recorded repository content, not every important file.
- Assuming automatic means verified. Check the last successful operation and inspect the destination.
- Keeping every layer under one account. One access problem can block all copies.
- Backing up generated clutter but missing source files. Protect the irreplaceable source and document what can be regenerated.
- Never testing recovery. A plan remains an assumption until a restoration succeeds.
Do this now
Pick one course or project folder. Fill in the three-layer plan and name one failure that each layer handles. If a layer is intentionally absent, record why and what risk remains.
Next, perform a small restoration test so the backup layer produces evidence rather than confidence alone.
Log what you learned
Record only:
- Result: What did the action produce?
- Evidence: What observation, test, or source supports that result?
- Next action or unresolved question: What should happen next?